

AI-Ready Data: Steps to Prepare Your Master Data

- Key Takeaways
- Introduction
- What Is AI-Ready Data?
- Why Should Your Data Be Ready for AI?
- What Blocks Data Readiness for AI?
- What Are the Components of AI Readiness?
- Is Your Data Ready for AI?
- How to Make Your Data AI-Ready: 5 Steps to Follow
- Measuring the Success of Your AI-Ready Data Management Plan
- Ensure Data Readiness for AI with Profisee
- Frequently Asked Questions
- About the author
Contents
- Key Takeaways
- Introduction
- What Is AI-Ready Data?
- Why Should Your Data Be Ready for AI?
- What Blocks Data Readiness for AI?
- What Are the Components of AI Readiness?
- Is Your Data Ready for AI?
- How to Make Your Data AI-Ready: 5 Steps to Follow
- Measuring the Success of Your AI-Ready Data Management Plan
- Ensure Data Readiness for AI with Profisee
- Frequently Asked Questions
- About the author
Key Takeaways
- AI-ready data is the records that have been cleansed, labeled, validated and transformed into a high-quality, structured format suitable for immediate and effective training or deployment by an AI tool.
- The components of AI readiness include data quality, accessibility, governance, completeness, standardization, unification and lineage.
- To make your assets AI-ready, you need to cleanse, normalize, deduplicate, enrich and manage master data.
- Profisee Master Data Management (MDM) helps you break down information silos and enforce data quality standards, ensuring your assets are consumable for your AI use cases.
Introduction
AI tools are only as effective as the information they have access to. And because master data (core business records about customers, products, locations and more) governs the relationships every other system depends on, its quality sets the ceiling on what AI does for you. When your enterprise has poor data, you spend the AI budget on remediation rather than on insight, and the automation you planned never reaches production.
This article is your starting point to learn what data readiness for AI requires, how to audit your own and the five steps that will get your records ready for this launch.
What Is AI-Ready Data?
AI-ready data is the information that’s been systematically prepared to enable safe, efficient and effective consumption by AI tools. MDM software transforms raw, siloed records into a cohesive, reliable asset called master data: A clean, consistent, well-structured and consumable asset that AI agents or tools process without bias or misinterpretation.
By using AI-ready data management solutions, you provide the context and consistency that machine learning models need. A master data management (MDM) tool like Profisee matches, merges and standardizes information to implement a single source of truth for each of your records, ensuring predictions and decisions reflect the business’s reality.
Understand why most leaders still don’t get AI adoption. Listen to our CDO Matters Podcast.
Why Should Your Data Be Ready for AI?
You should prepare your master data because the accuracy, trustworthiness and business value of your AI initiatives depend on it. When you have fragmented or inconsistent enterprise records, AI systems struggle to generate meaningful insights. Working on asset readiness for AI also reduces the amount of remediation required every time a team moves from experimentation to production. Shared, governed information domains let new use cases start from a trusted base instead of rebuilding customer, product or supplier logic independently.
The cost of skipping the organization of your assets becomes greater at scale. Gartner predicted that through 2026, organizations would abandon 60% of AI projects not supported by AI-ready data. The problem isn’t simply that poor information can reduce model accuracy. Inconsistent records also make systems harder to govern, explain, integrate and reuse.
The benefits of MDM for AI data readiness include:
- Accurate AI outcomes: Clean, standardized and consistent data reduces the risk of models hallucinating or otherwise producing unreliable or misleading outputs.
- Accelerated time to value: You start realizing results from your AI initiatives much faster when your data is ready for AI as opposed to when it’s still siloed, duplicated and inconsistent.
- Scalability: Consistent, trustworthy data enables organizations to scale AI projects from proof of concept to enterprise-wide implementation.
- Faster production deployment: Teams spend less time reconciling entities, definitions and access rules for every new project.
- Greater reuse: A mastered customer or product domain supports analytics, operational applications and multiple AI use cases.
- More effective governance: Clear ownership, lineage and validation rules make it easier to understand what information an AI system used and whether it was authorized to use it.
What Blocks Data Readiness for AI?
Most data readiness problems begin upstream of the model. They come from how enterprise systems represent, update and govern the business entities an AI application depends on.
Fragmented Records Across Source Systems
The same customer sits in a CRM, a billing platform and a support desk, spelled differently and showing a different address in each tool. An AI system reading all three treats them as separate accounts, then splits the revenue history and the risk score between them.
Matching and survivorship rules solve the issue by collapsing those rows into one authoritative version. When AI agents or tools read from the unified source, they understand which records belong together and which attributes should form the trusted version.
Missing Hierarchies Between Entities
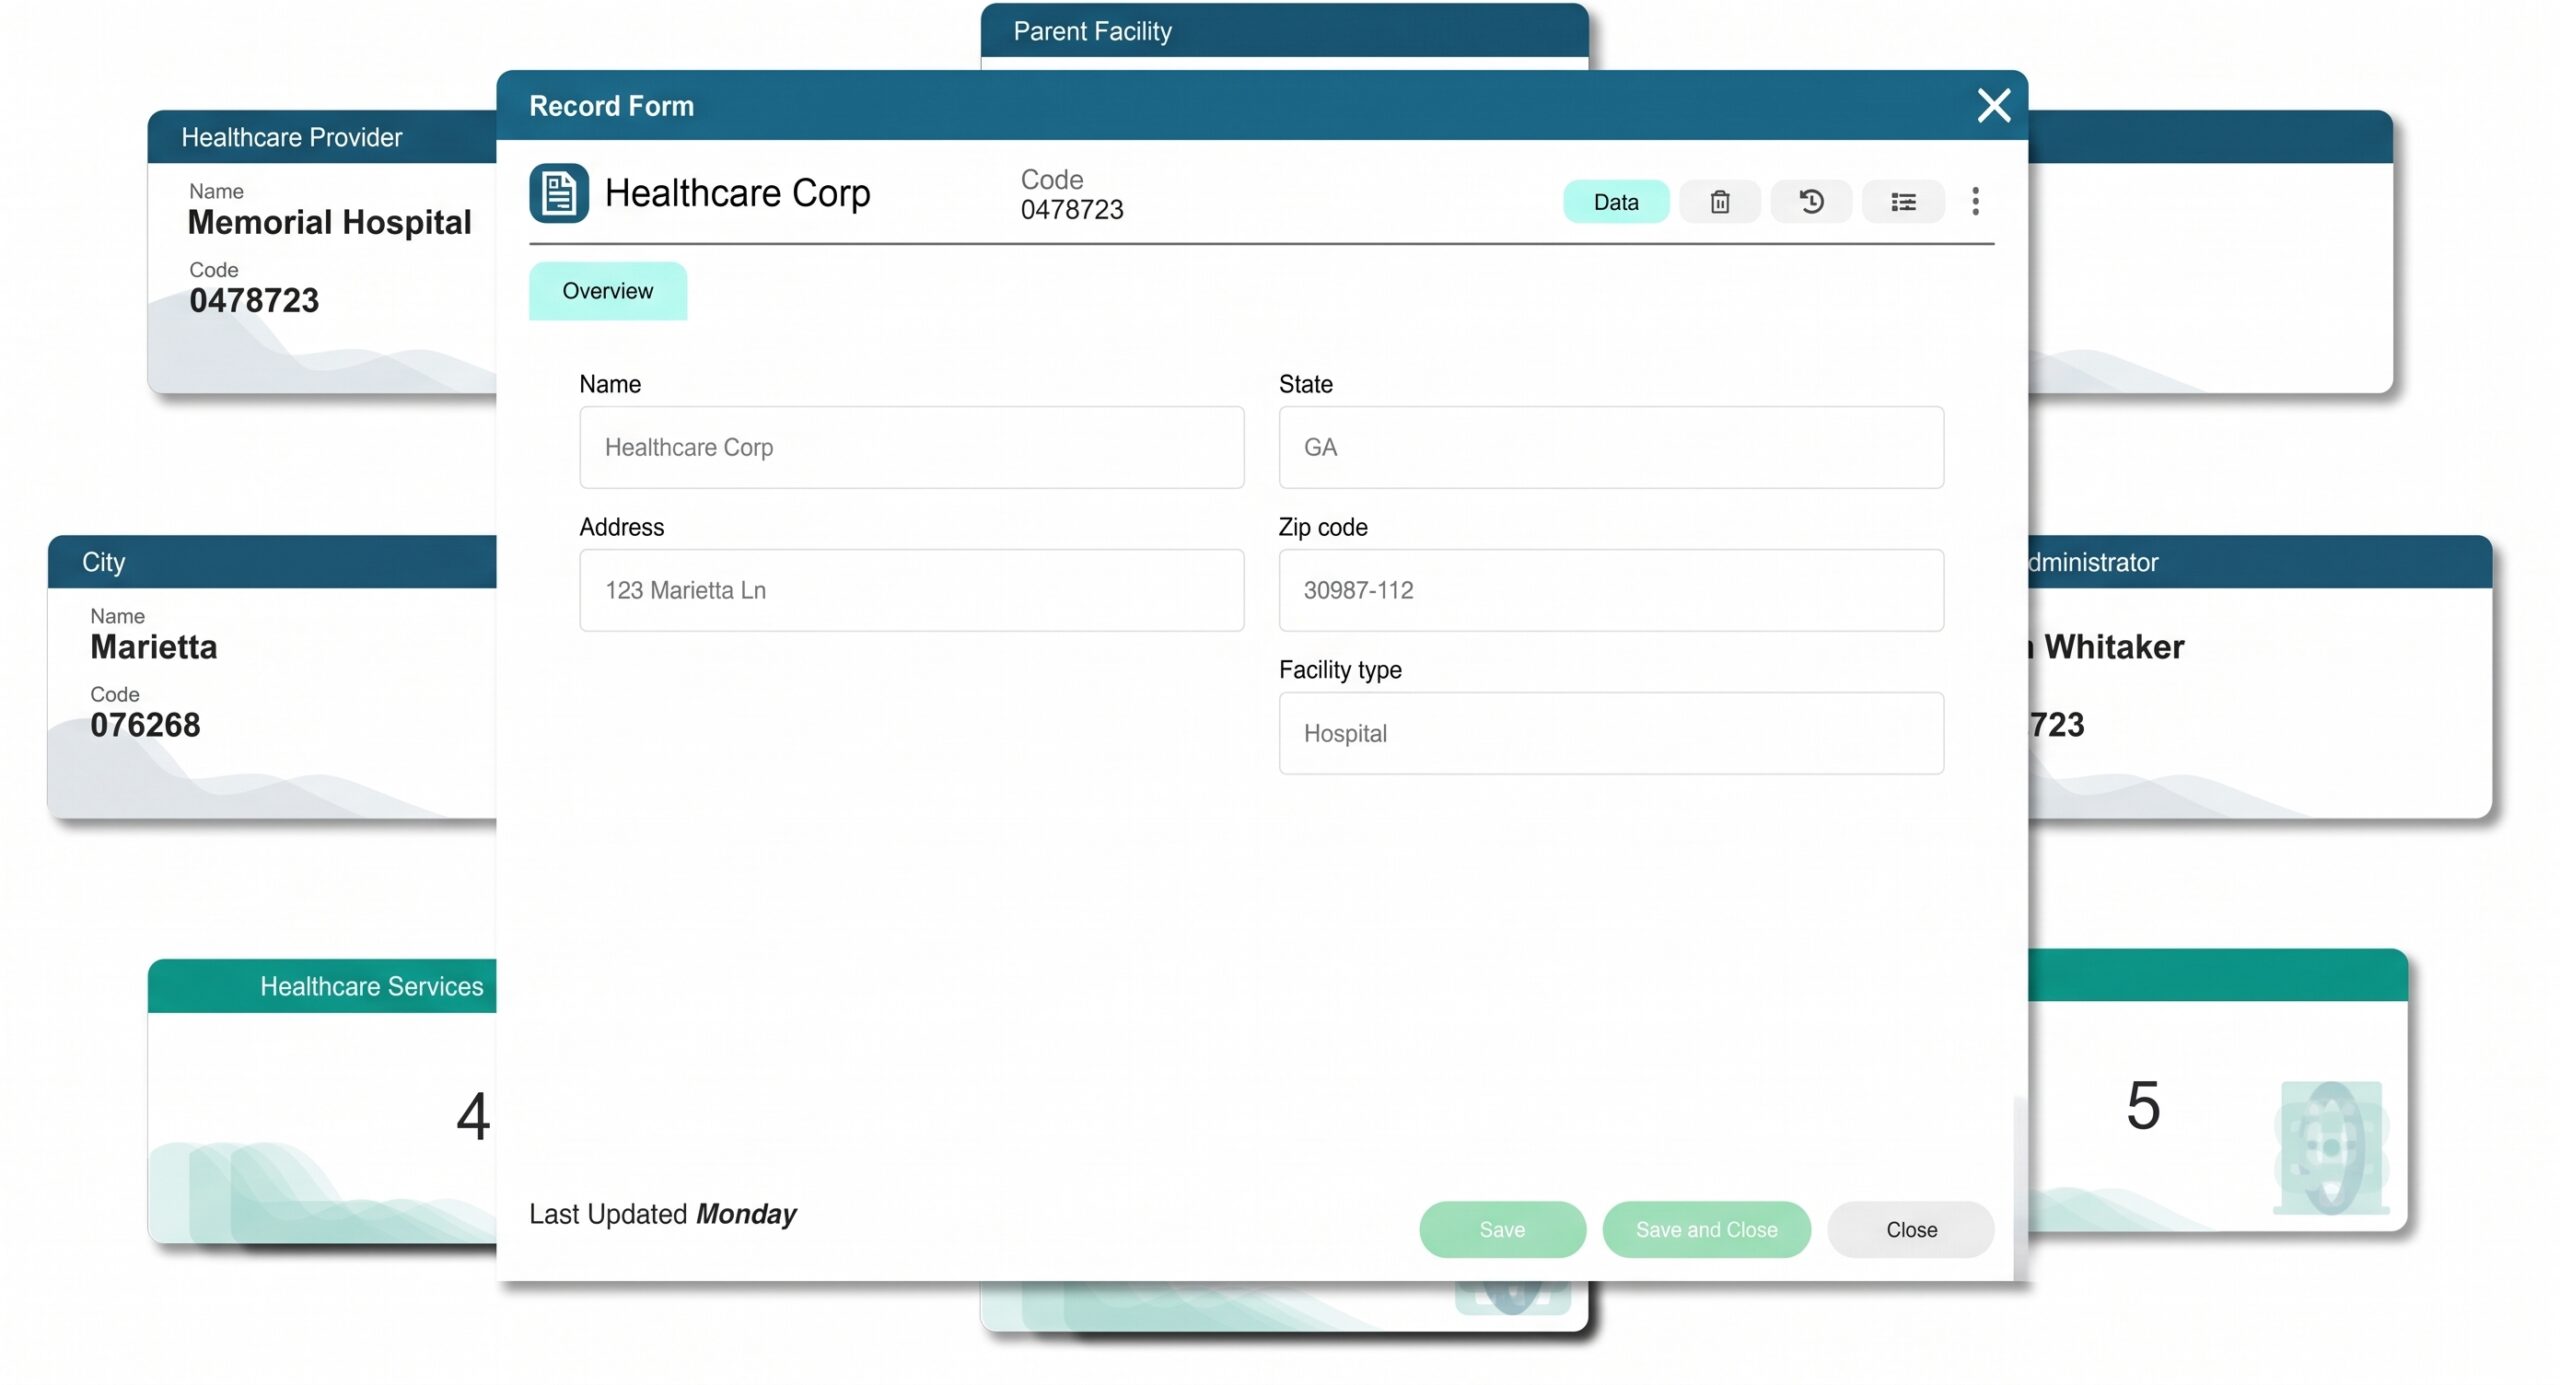
Even if a single data record is correct on its own, it can still be misleading if it is missing broader context. Customer information without its corporate hierarchy, a product with no category relationships or a provider missing the correct facility affiliation can lead to decisions made at the wrong organizational or analytical level.
Relationship management helps AI applications move from isolated records to the business structures those assets represent. The Profisee relationship management dashboard provides additional context about the subsidiary, the parent it reports to and the entities alongside it in one frame. This unified view is especially important for cross-sell, procurement, risk, healthcare and other use cases where relationships affect the correct action.
Batch Pipelines That Handle AI Stale Records
Not every AI use case requires real-time information, but the required freshness should match the decision it supports. The issue is not batch processing itself, but when the delay exceeds what the decision can safely tolerate. A 12-hour lag might be irrelevant for trend analysis but critical for credit approvals or service routing, where the system acts on the most recent state it can see.
Data teams should define acceptable latency per use case and refresh mastered records within that window to ensure decisions use valid information.
Undefined Ownership When Quality Breaks
When a field starts arriving empty, somebody has to notice and fix it. Without a named owner per domain, whoever the bad output embarrasses rediscovers the problem, weeks after it started.
Stewardship software puts a named person on each domain and gives them a queue, which turns remediation into a routine instead of a fire drill.
No Shared Definition of a Business Term
Finance counts an active customer one way and the revenue team counts it another, so two AI outputs disagree and neither one is wrong. Agreeing on the definition once, then enforcing it in the MDM platform that distributes the record, settles the disagreement at its source.
Check out our selection of data management solutions that solve your shared definition issue.
What Are the Components of AI Readiness?
AI readiness relies on seven interconnected components, most of which you’ve probably heard of if you’re familiar with the dimensions of data quality.
1. Data Quality
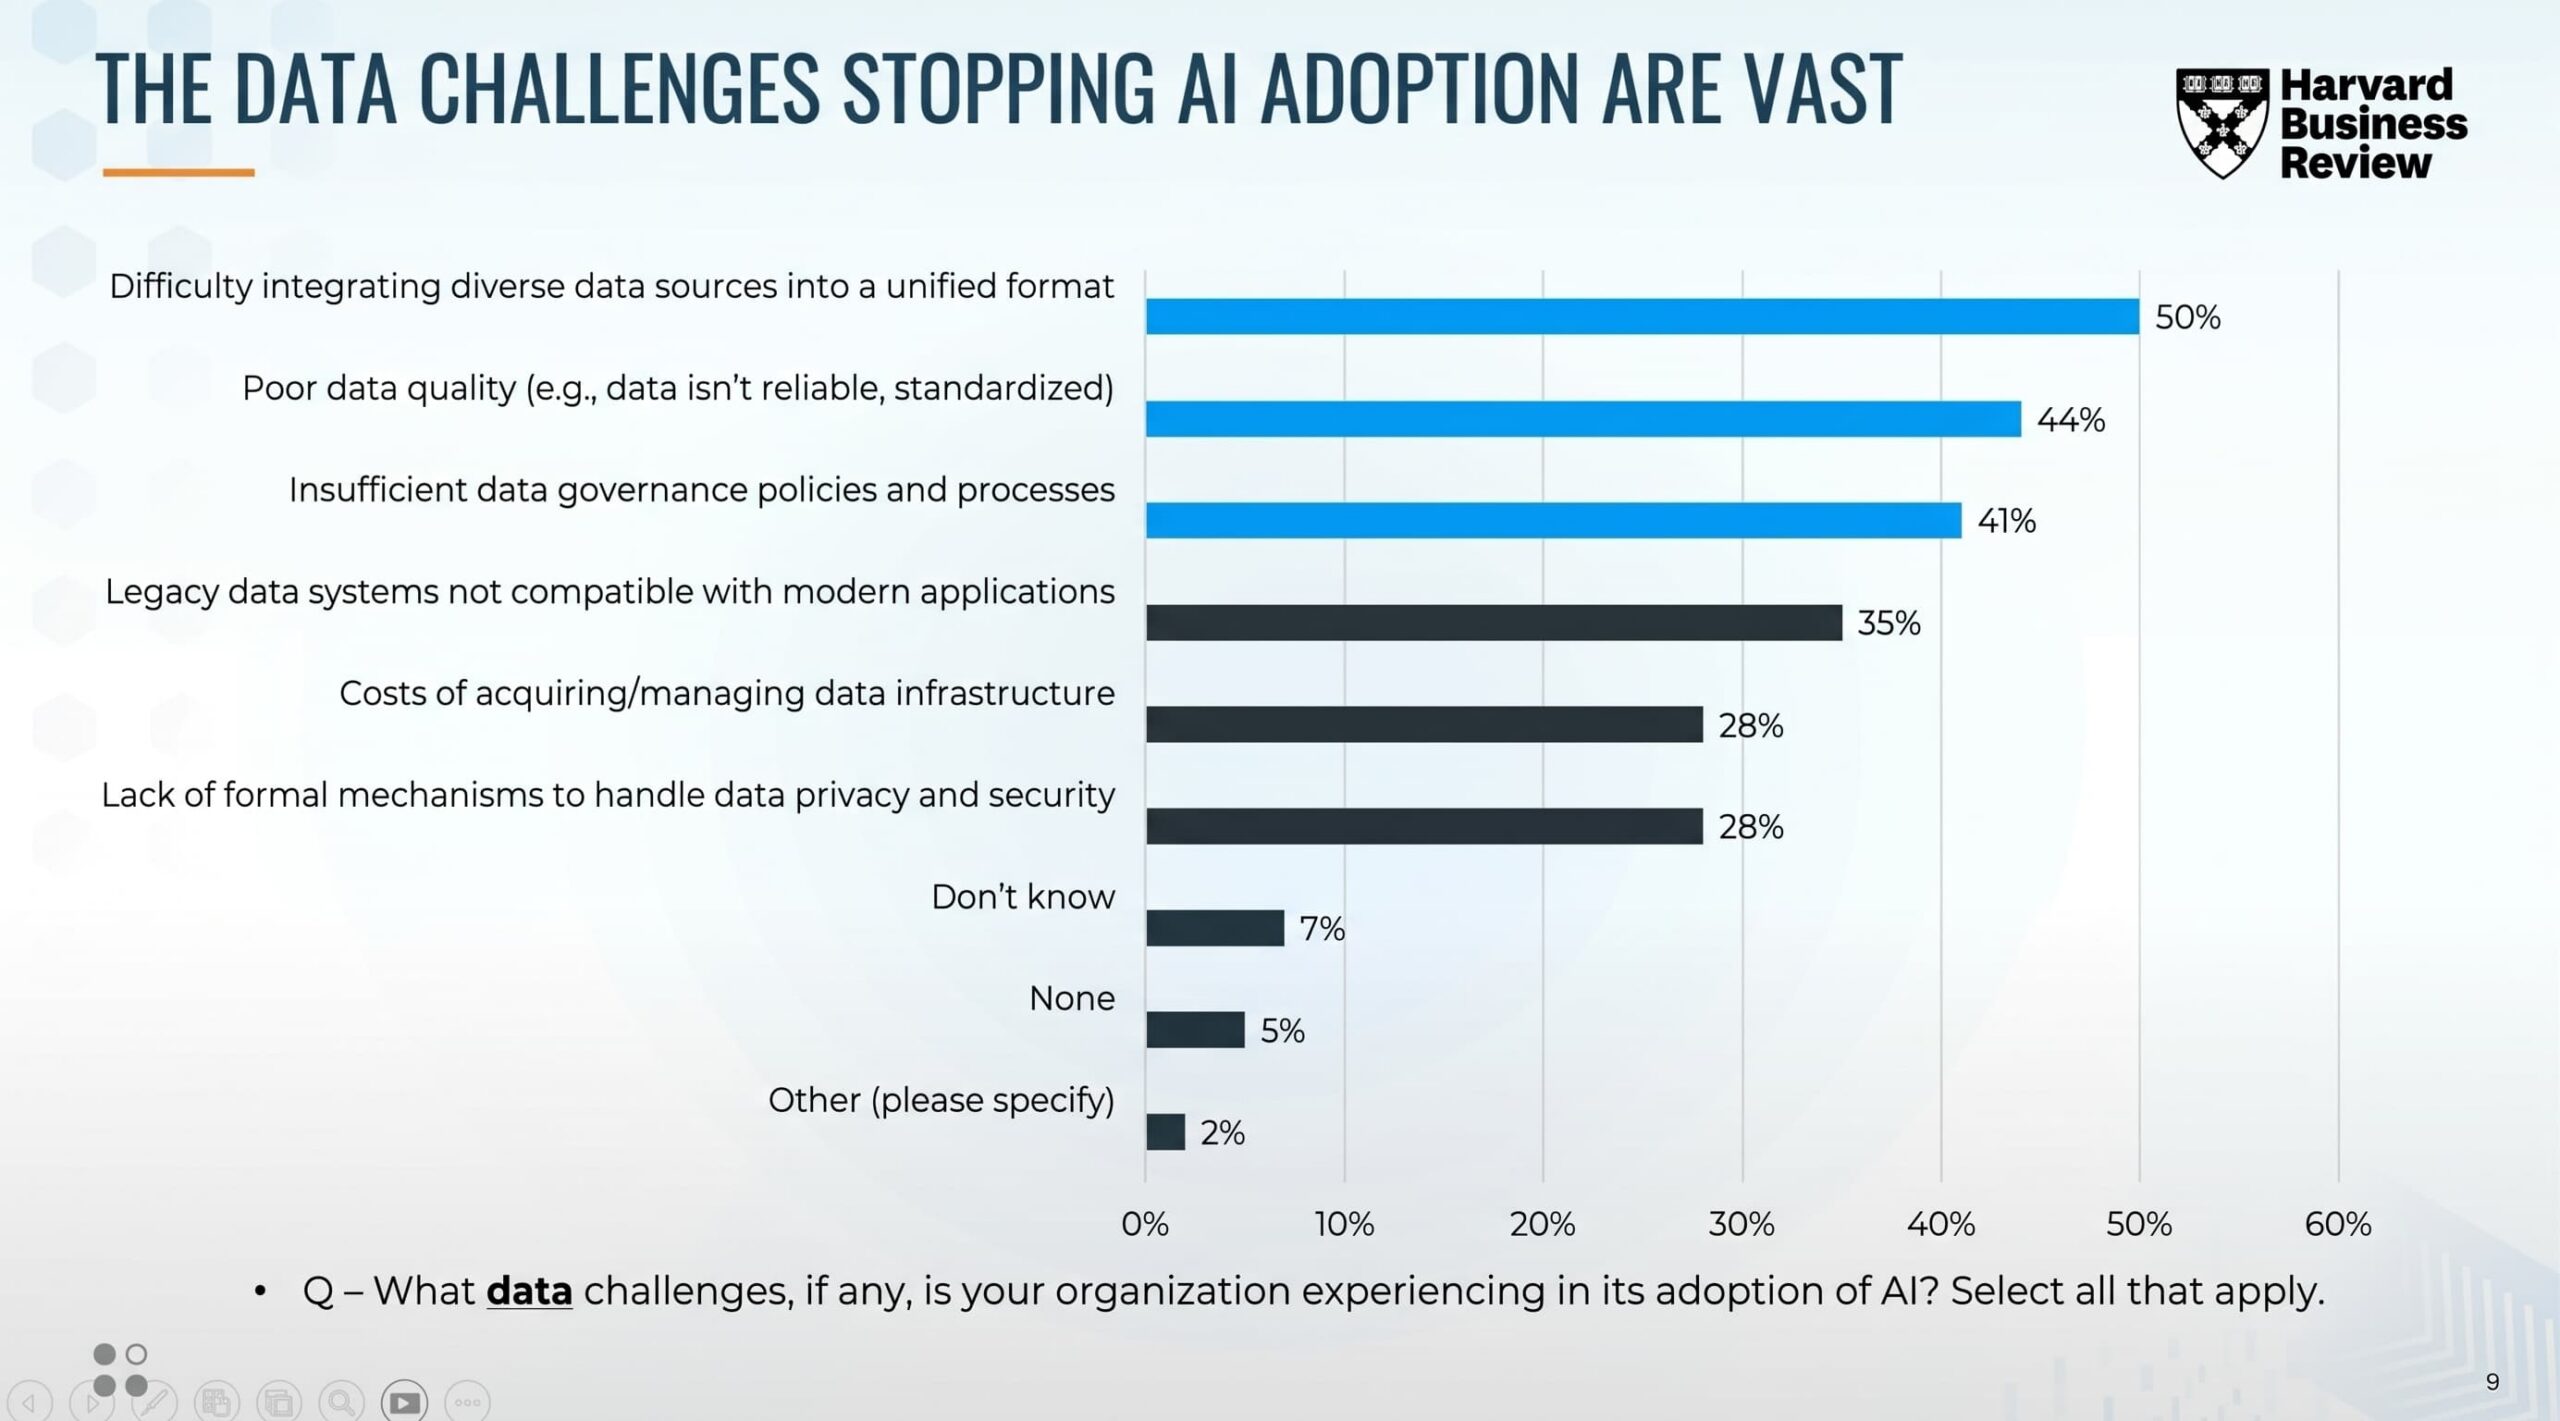
According to a Harvard Business Review survey, 44% of organizations adopting AI cite poor data quality as a challenge. These standards for machine learning are even more rigorous than those for traditional analytics because AI agents act autonomously. As it becomes more common for AI tools to take action without direct human intervention or oversight, it’s extremely important to make sure the master records powering such tools are unified, accurate, timely, unique and consistent.
Enterprise data quality requires records to be:
- Unique: Duplicate data should be merged to retain only the most accurate, up-to-date information
- Complete: All critical fields need to contain valid values
- Consistent: Records should be uniform across workflows so that two systems don’t show conflicting information about the same entity
- Precise: Data needs to contain the appropriate level of detail
- Accurate: Information should correctly represent real-world entities and events and be verified against real-world values
- Timely: Records need to be available when needed and accessible to the AI tools that run them
2. Data Accessibility
Accessibility includes integration, interfaces, security controls and the ability to deliver mastered records to consuming systems. AI tools need frictionless access to relevant assets across the enterprise. Deloitte found that 72% of leaders name the lack of a unified and accessible data foundation as a reason they can’t scale AI agents. Information trapped in silos or locked in incompatible workflows can’t fuel applications, regardless of its quality.
Here’s how to ensure accessibility to your AI initiatives:
- Eliminate data silos that trap information in departmental systems
- Implement unified data platforms that provide consistent access patterns
- Establish clear catalogs for users and AI systems to discover available information
- Use APIs and interfaces that enable real-time record consumption
Keep learning and discover what makes data consumable.
3. Data Governance
Governance defines who owns information, what standards records need to meet, who may access it and how teams resolve exceptions. Without data governance and quality, your AI outputs remain inconsistent, poorly understood and unreliable.
Data governance frameworks are critical for defining rules, processes and information ownership across organizations. Effective governance for AI-data readiness establishes:
- Ownership: Defined accountability for each asset
- Definitions: Consistent taxonomies across the organization
- Policies: Clear rules governing access, usage and security of information
- Processes: Active monitoring and remediation of data quality
See data governance use cases and examples.
4. Data Completeness
A record is only complete when it contains the attributes required for its intended use. A recommendation model may need purchase history and customer segment, while an automated onboarding process may also require legal entity information, risk status and consent. AI models require comprehensive data sets to generate accurate insights. Missing information creates blind spots that lead to biased or incomplete outputs.
To ensure your data sets are complete, check if they count on:
- Fully populated critical attributes across records
- Sufficient historical data for pattern recognition
- Linked related information from multiple sources
- Comprehensive data coverage across all business domains
- Metadata to provide important context about information
5. Data Standardization
Data standardization ensures that information follows consistent formats, structures and conventions across all systems and sources. Without this process, AI systems struggle to interpret records correctly, leading to reduced accuracy and reliability.
Standardization covers four elements:
- Formats: Uniform for common data elements (dates, addresses, names)
- Units: Consistent measures and currencies across systems
- Codes: Harmonized classifications throughout the organization
- Naming conventions Aligned to eliminate ambiguity
6. Data Unification
Data unification brings together information from disparate sources into a unified view that AI systems can use. Modern AI applications require context that spans multiple systems — for example, customer records from customer relationship management (CRM), transaction history from enterprise resource planning (ERP), interaction history from service platforms and behavioral information from digital channels.
Effective data unification delivers:
- Entity views that connect all information about customers, products or assets
- Cross-system relationships that reveal how information connects across data domains
- Real-time flows, which ensure AI operates with current information
- Semantic consistency to align concepts across all sources
7. Data Lineage
Lineage records where each value came from, what changed it and which systems consumed it. When an AI output looks wrong, this history is what lets you or your agents trace the number to a source system instead of guessing which of six feeds introduced the error.
Lineage tracking investigates four elements:
- Sources: Which system contributed each value and when
- Transformations: The rules that changed a value between the source and the golden record
- Consumers: Which systems, models and agents read the record
- Retention: How long the history stays queryable for an audit
Explore how a medallion architecture preserves that trail in the record’s metadata.
Is Your Data Ready for AI?
How to Make Your Data AI-Ready: 5 Steps to Follow
Preparing your data for AI is an ongoing process. Consider these five practices a baseline plan for keeping important business records trustworthy as source systems and use cases change:
1. Data Cleansing
Start by detecting and resolving errors within datasets, such as misspellings, null values and invalid entries. Data cleansing establishes a baseline level of quality and trustworthiness that all subsequent AI operations depend on. Organizations typically automate this process with a data quality platform that flags anomalies, validates formats and corrects common errors in enterprise records.
2. Data Normalization
Normalization converts data into a unified, standard format, securing structural consistency so AI models can process information efficiently and accurately. This step includes standardizing date formats, converting measurement units, aligning naming conventions and ensuring consistent record types across all fields.
3. Data Deduplication
With deduplication, you identify and merge records that refer to the same real-world entity despite variations in the raw assets. This step prevents AI models from making decisions based on duplicate or conflicting information, which can skew results and inflate the perceived importance of specific data points.
4. Data Enrichment
Data enrichment enhances existing assets with additional information from internal or external sources, providing AI systems with richer context for generating insights. This process might include appending demographic information, incorporating third-party intelligence or linking related records across AI-ready databases to create a more complete picture.
5. Master Data Management (MDM)
Master data management takes siloed, duplicated, inconsistent assets and creates unified, unique, clean and standardized information for golden records — single, trusted versions of critical entities (customers, products, etc.) that connected systems can access. An MDM platform like Profisee also manages asset relationships and distributes trusted information back to the AI applications that need it.
See how Profisee helps you build AI-ready data.
Measuring the Success of Your AI-Ready Data Management Plan
Ensure Data Readiness for AI with Profisee
Frequently Asked Questions
About the author
Benjamin Bourgeois
B, Bourgeois (02/11/2026) AI-Ready Data: 5 Steps to Prepare Master Data | Profisee
Tags
trending posts